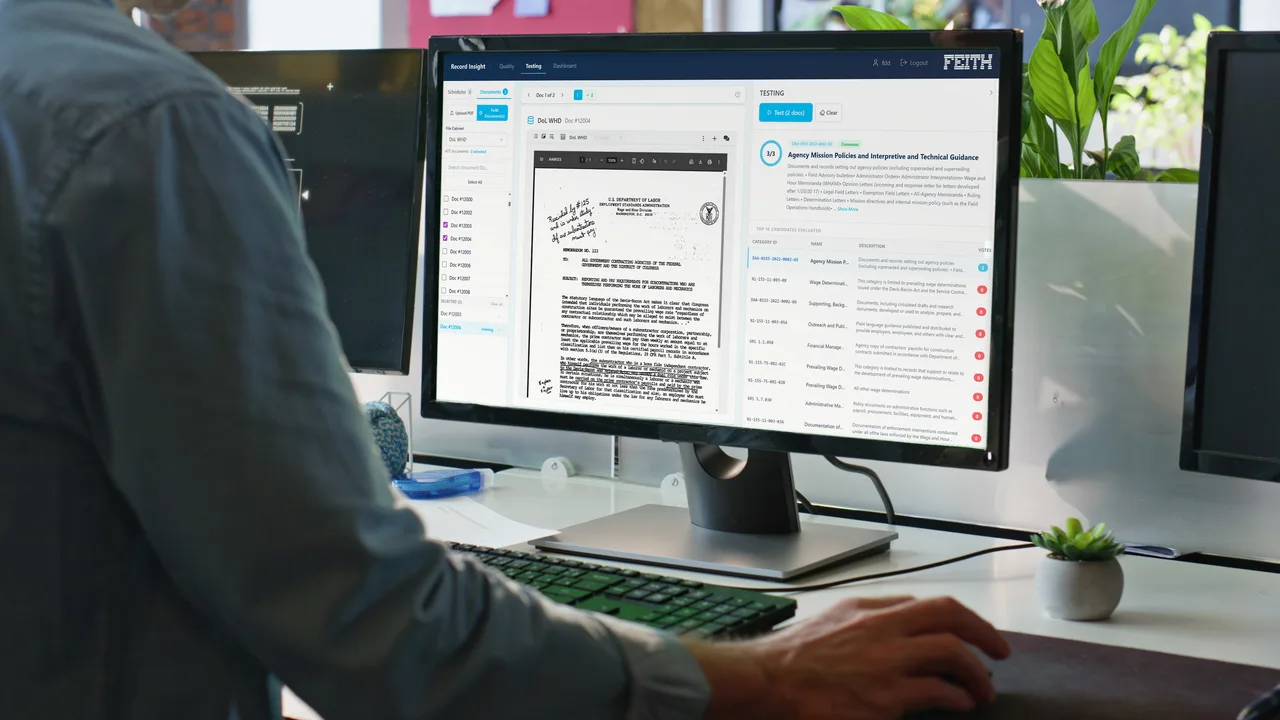
Unstructured files in. Structured data out.
Feith's AI reads your documents, pulls out the entities, dates, and dollar values that matter, and fills in metadata fields on its own, turning dormant PDFs into data you can search, route, and report on.
Your most important facts are locked inside documents.
Agencies sit on millions of files, and the facts that matter live inside them: an expiration date, an approval signature, a dollar amount. Pulling them out by hand doesn't scale past a few thousand files, so the rest stays dark: invisible to search, dashboards, and compliance review.
Feith reads them for you.
Describe what you need in plain English.
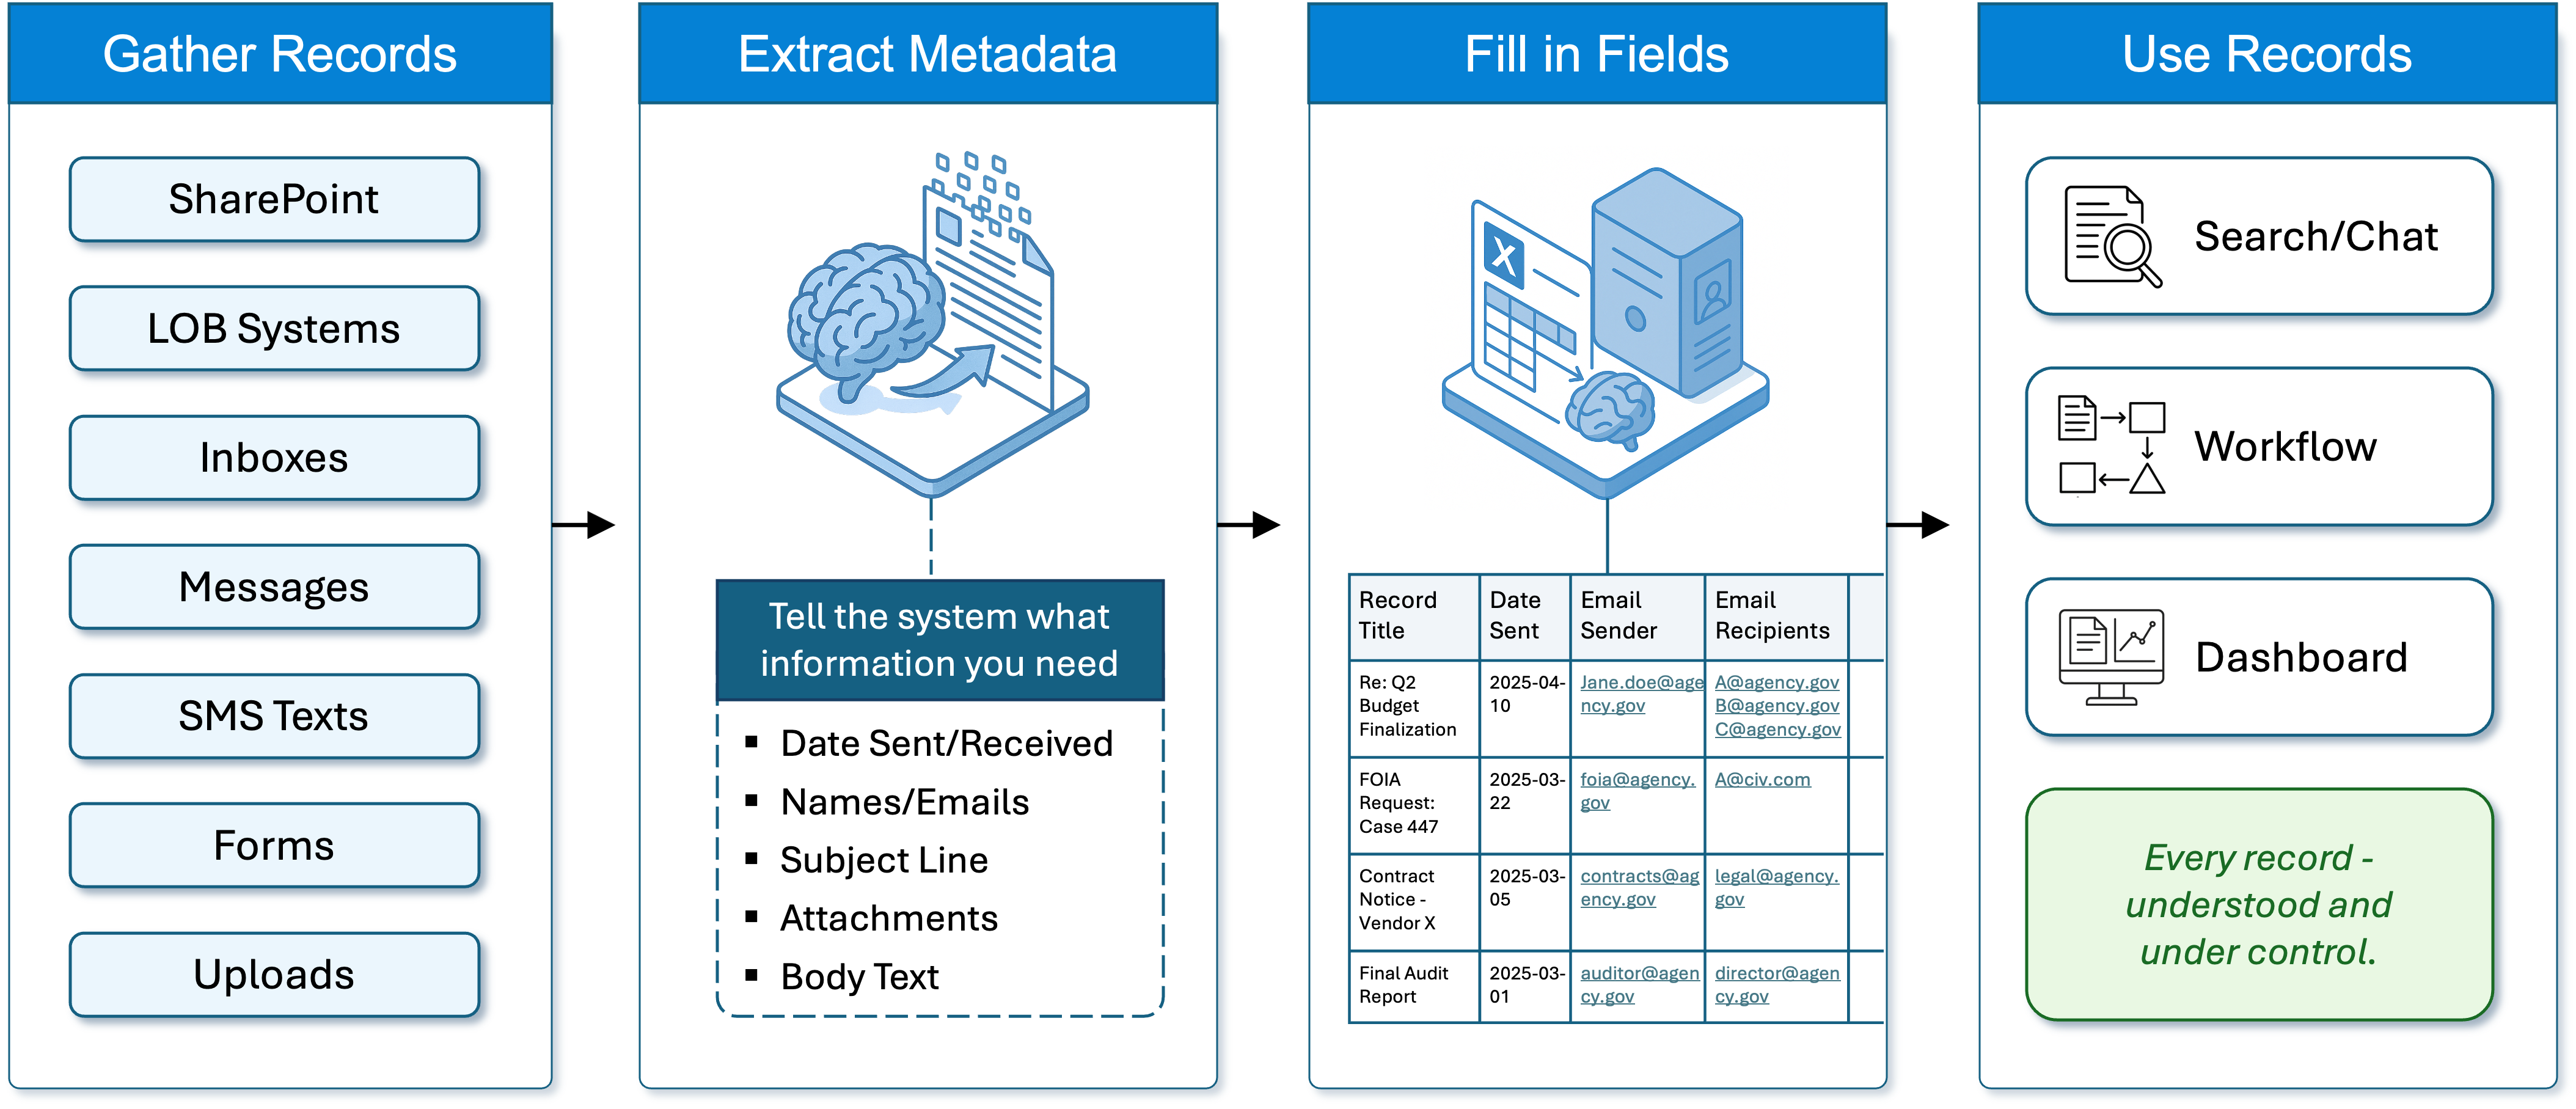
No rules to write, no templates to maintain. Tell the extractor what to look for, and it scans every document to find and pull it, then turns each value into a metadata field you can use.
Find each contract's termination date, total value, and counterparty.
- Termination date
- Total value
- Counterparty
Each becomes a field: searchable, sortable, ready for a workflow.
Reads context and meaning
Traditional indexers break when the formatting varies or a value sits somewhere unexpected. Feith's AI reads a document the way a person does, recognizing dates, names, and dollar amounts across different layouts, phrasings, and document types.
Builds the metadata fields for you
The AI creates the matching field, say, “Training completion date,” and populates it across every relevant document. Track status, remind anyone overdue, and roll it all up into a view of the whole organization.
Engineered for every environment.
Scales to millions of files
The architecture scales with no fixed ceiling on documents or users, on-premises, in a private cloud, or in a FedRAMP-authorized government cloud.
Frees your experts
Automated extraction reduces manual data entry, so specialists spend more of their time on judgment calls, and you get structured metadata at intake.
Safe for federal data
Zero hallucination, zero data leak. Every new capability stays in our controlled validation pipeline until it meets the bar for use with federal records.
Routing that reads the content.
Extracted metadata drives what happens next. The system spots a legal-action flag, a security issue, a payment status, or a contract milestone, and routes the document accordingly, escalating the critical items and automating the routine ones.
A legal-action flag, a security issue, or a missed deadline is surfaced and routed to the right person.
Standard acknowledgements and status updates are drafted for staff to review and send.
Dashboards built on live, sourced data.
Once it's extracted, metadata can be aggregated, filtered, and charted. Because every value is pulled straight from the content, the data stays current and tied back to its source, giving real-time visibility into things that used to be buried, with no manual review.
Put your documents to work.
Request received.
Thanks. We'll reach out shortly to set up your demo.